
SageMaker Inference now supports Multi-Instance GPU to maximize GPU utilization for model endpoints
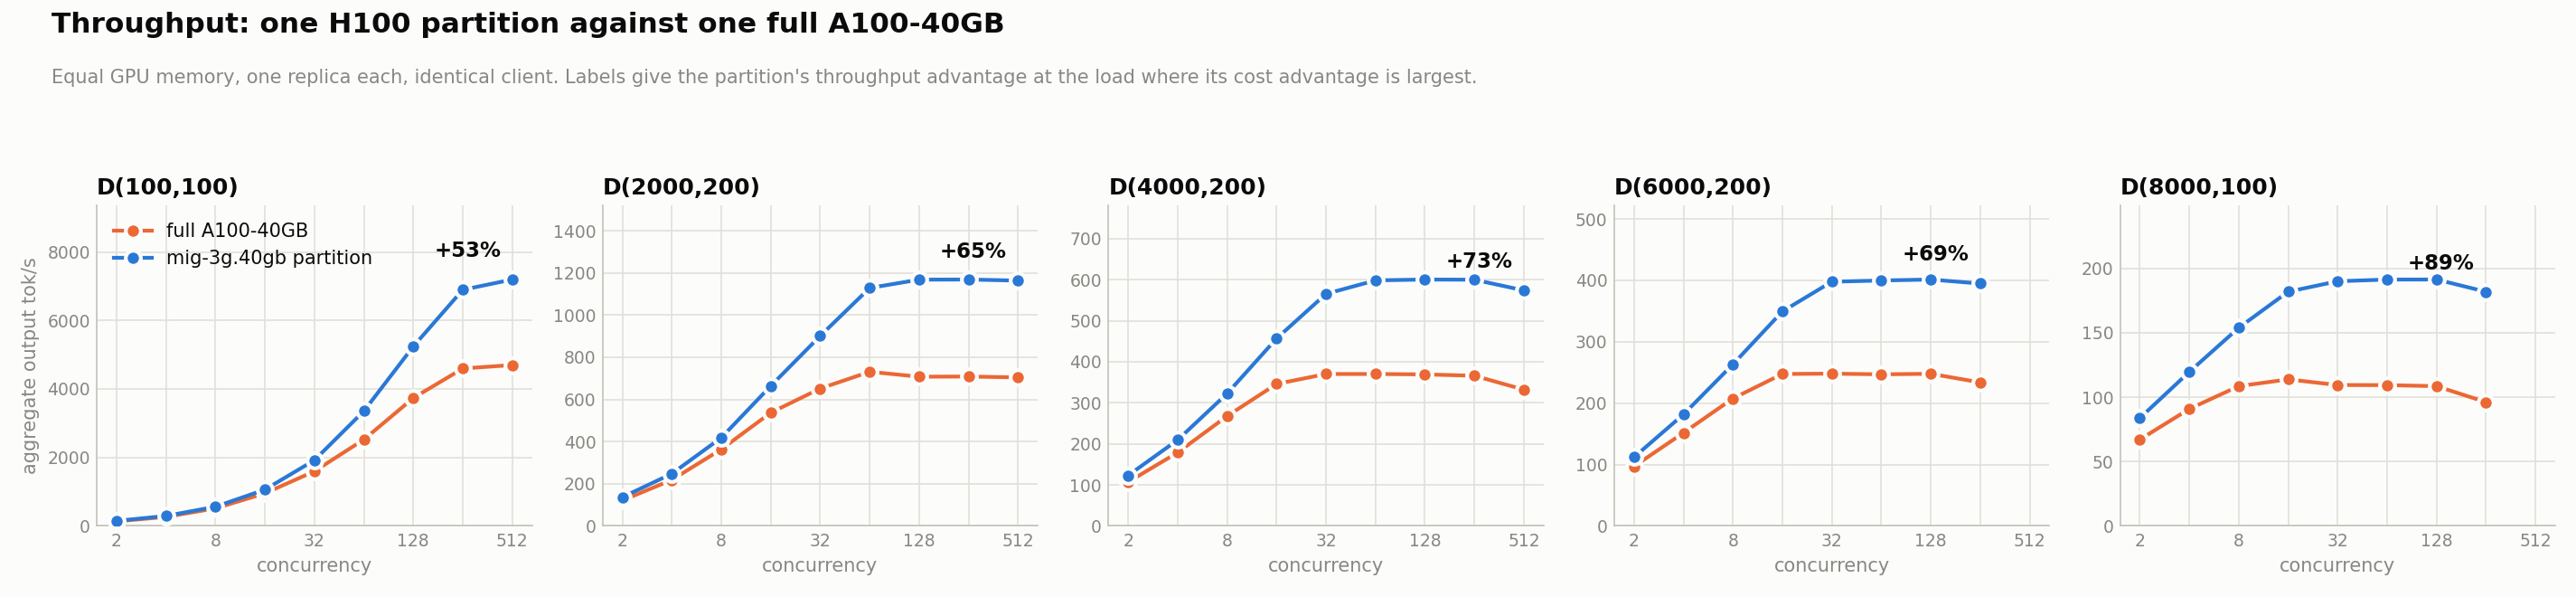
When you deploy a model to a GPU endpoint, the smallest unit of GPU you can request is one whole accelerator. This constraint can cost you twice. First, you can’t host more models on an instance than it has accelerators. An ml.p4d.24xlarge has eight A100s, so it holds eight models, whether each one needs 40 GB or…
Excerpt provided by AWS Machine Learning via its public feed. Full reporting belongs to the original publisher.
Read the full story on AWS Machine Learning