
Scout Before You Route: Predicting Task Success and Token Count from a Small LLM Prefill
arXiv:2611.09028v1 Announce Type: new Abstract: Routers typically choose a model per query by trading predicted correctness against cost. Most price each model at a fixed cost, as if every query used the same number of output tokens, but the output length of reasoning models varies by an order of magnitude across…
Excerpt provided by arXiv cs.AI via its public feed. Full reporting belongs to the original publisher.
Read the full story on arXiv cs.AI
Related coverage
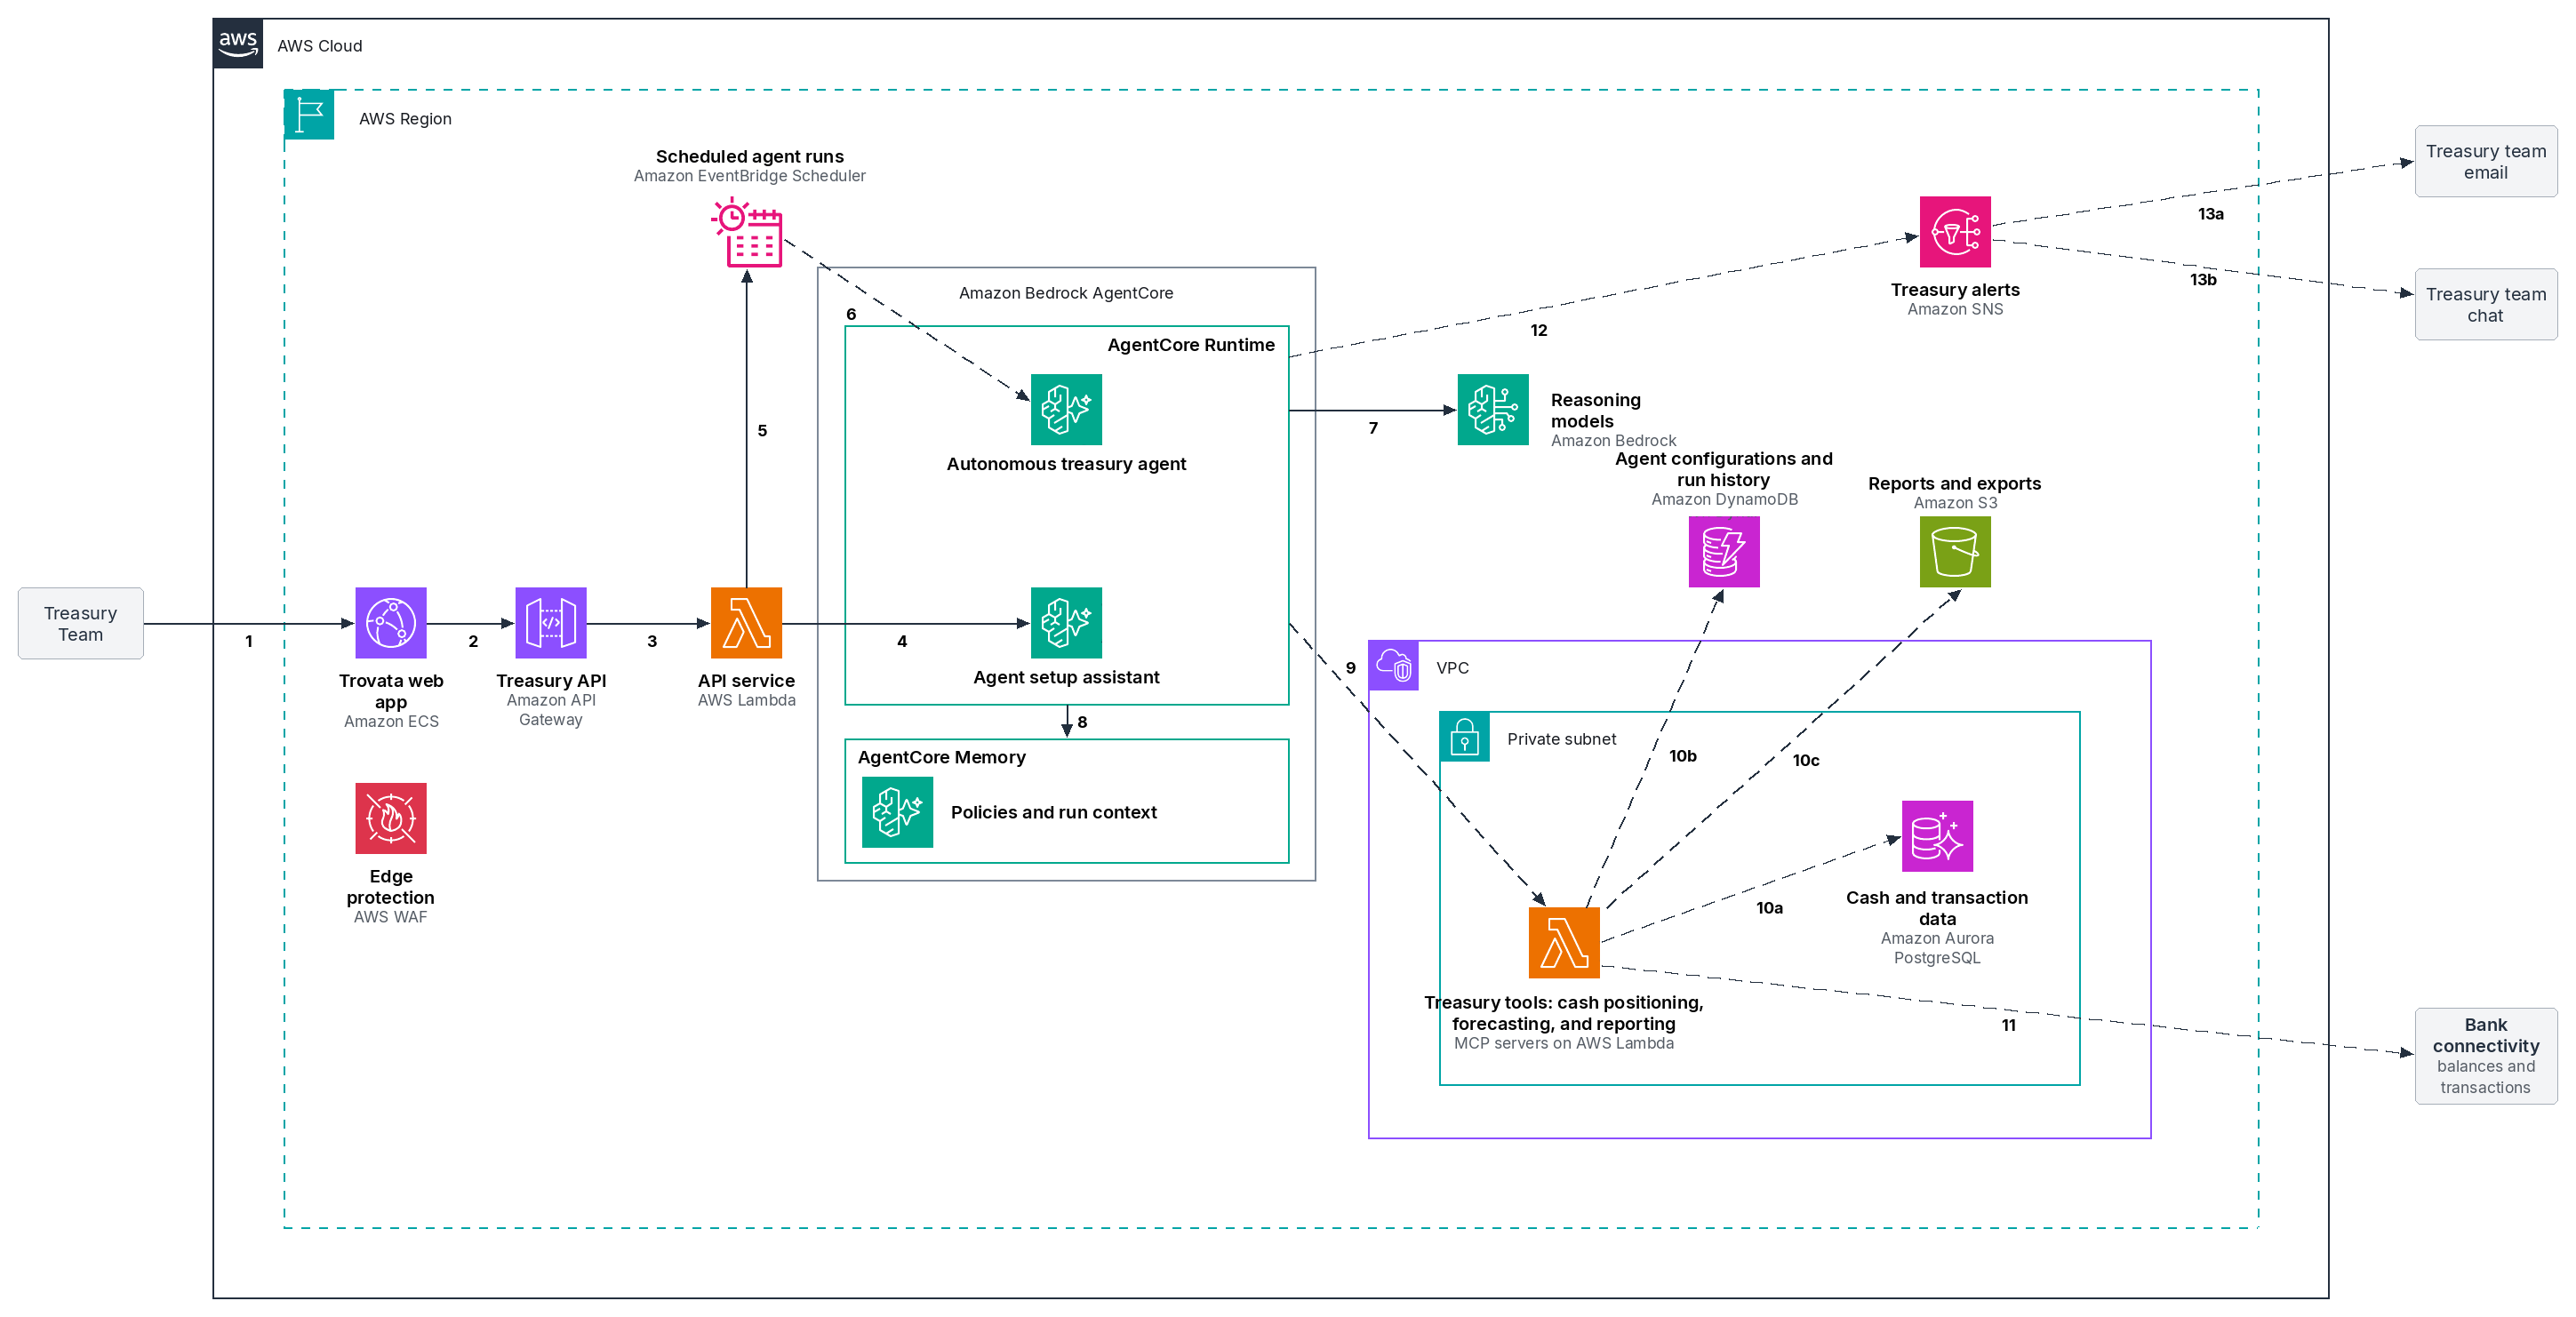
AWS Machine Learning · 43m ago
Autonomous treasury agents: How Trovata built an AI-native solution on Amazon Bedrock and AgentCore

The New York Times — Technology · 1h ago
Who Is Alice Huang, the Woman in the Middle of Nvidia’s Spy Scandal?
The Verge AI · 4h ago
Anthropic targets $1.4 trillion IPO
BBC · 6h ago
Anthropic to raise $64bn in major stock market listing