
AutoEMatic: Runtime-Adaptive Mixed-Precision LLM Inference via Automatic Exponent-Mantissa Refinement
arXiv cs.AI · Akshat Ramachandran, Reena Elangovan, Rangharajan Venkatesan, Charbel Sakr, Tijmen Blankevoort, Brucek Khailany, Tushar Krishna ·
arXiv:2611.10165v1 Announce Type: new Abstract: Existing LLM post-training quantization techniques determine precision before inference begins, yet the precision a model requires varies dynamically across prompts, layers, and inference phases. We present AutoEMatic, a full-stack co-design that adapts the precision…
Excerpt provided by arXiv cs.AI via its public feed. Full reporting belongs to the original publisher.
Read the full story on arXiv cs.AI
Related coverage

The Decoder · 43m ago
Gemini 4 Carbon arrives just in time to feel like yesterdays news in the fastest model cycle yet
Ars Technica AI · 4h ago
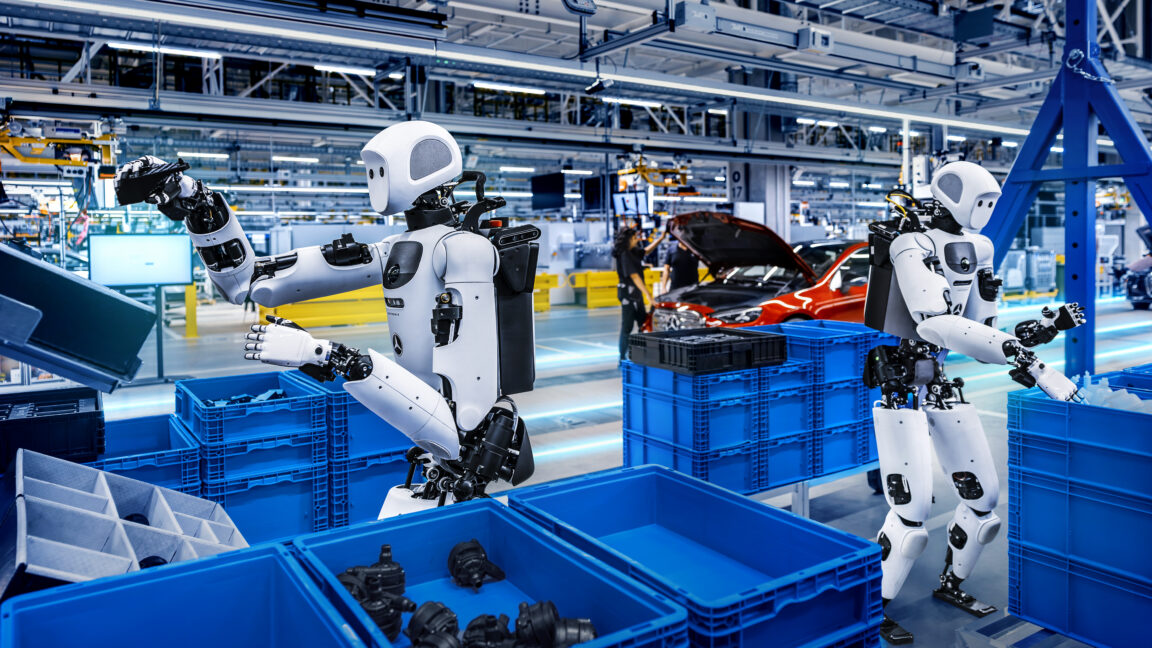
DeepMind reveals Gemini Robotics 2.5 and open safety benchmark "ASIMOV-jailbreak"

Google DeepMind · 6h ago
Introducing AlphaProof Code: a breakthrough in verifying complex software at depth
OpenAI · 10h ago
Closing the AI guidance gap in education